|
Shijie Zhou I'm a fourth-year Ph.D. candidate in Computer Science and Engineering at the University at Buffalo, where I'm advised by Changyou Chen. I also work closely with Ruiyi Zhang. During my Ph.D., I have interned at Adobe Research, working with Ruiyi Zhang and Jihyung Kil, and at the Qwen Large Model Application Team at Alibaba, working with Pengyu Cheng. Before that, I received my M.S. in Informatics from Penn State and my B.E. in Measurement Control Technology and Instruments from Soochow University. Email / CV / Google Scholar / Github |
|
ResearchMy research interests lie in large language models (LLMs) and multimodal LLMs (MLLMs), and their applications such as multi-turn agentic planning, GUI agents, and document understanding. Currently, I am working on self-evolving language models and reward signals for open-ended and verifiable tasks. |
|
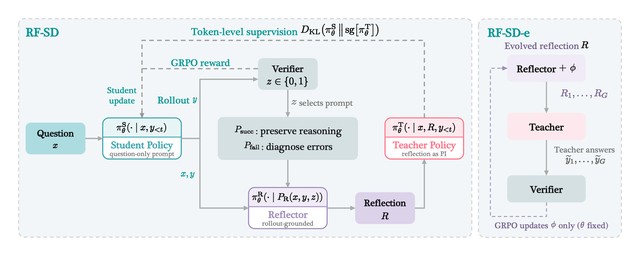
RF-SD: Reference-Free On-policy Self-Distillation via Self-Reflection
Shijie Zhou, et al. Under review, 2026 (work done at Qwen, Alibaba) A single policy plays student, reflector, and teacher: verifier-routed self-reflections replace external reference solutions as the teacher's privileged information for on-policy self-distillation. |
|
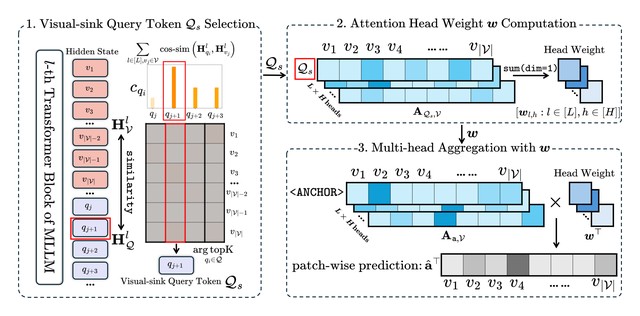
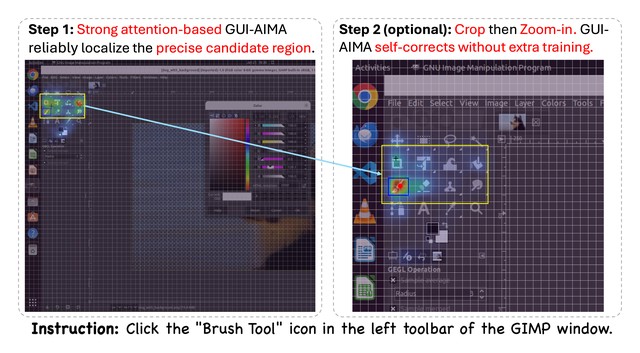
GUI-AIMA: Aligning Intrinsic Multimodal Attention with a Context Anchor for GUI Grounding
Shijie Zhou, Viet Dac Lai, Hao Tan, Jihyung Kil, Wanrong Zhu, Changyou Chen, Ruiyi Zhang ECCV, 2026 arXiv / code Instead of generating click coordinates as text, GUI-AIMA supervises an MLLM's intrinsic multi-head attention with patch-wise grounding signals through a learnable context anchor. Trained on only ~101k screenshots, GUI-AIMA-3B reaches 61.5% on ScreenSpot-Pro. |
|
TraceR1: Anticipatory Planning for Multimodal AI Agents
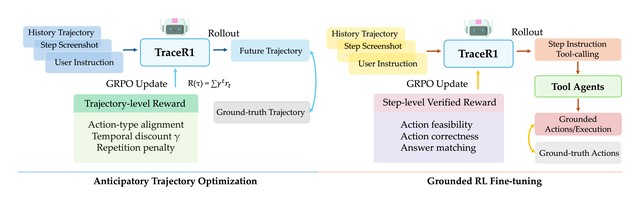
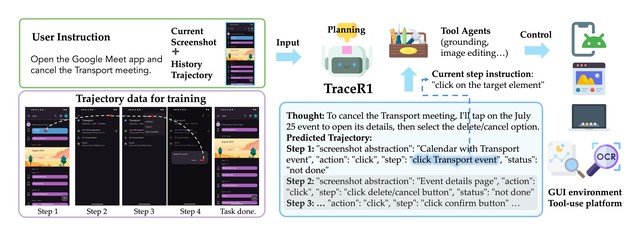
Yongyuan Liang, Shijie Zhou, Yu Gu, Hao Tan, Gang Wu, Franck Dernoncourt, Jihyung Kil, Ryan A. Rossi, Ruiyi Zhang CVPR Findings, 2026 paper / arXiv A two-stage RL framework that teaches multimodal agents to forecast future trajectories before acting: trajectory-level alignment first, then grounded fine-tuning with execution feedback from tool agents. |
|
Doc-AGround: Unveiling Inherent Visual Grounding in Multimodal LLMs for Text-Rich Images
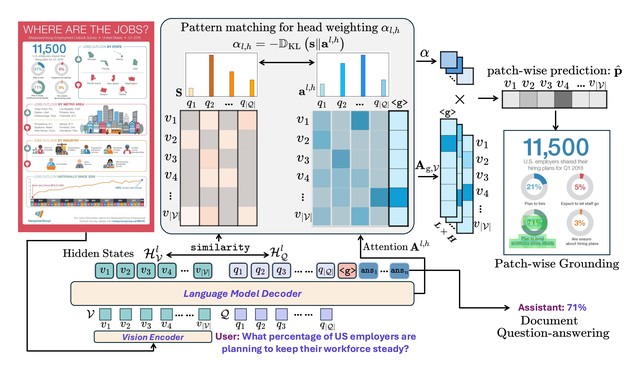
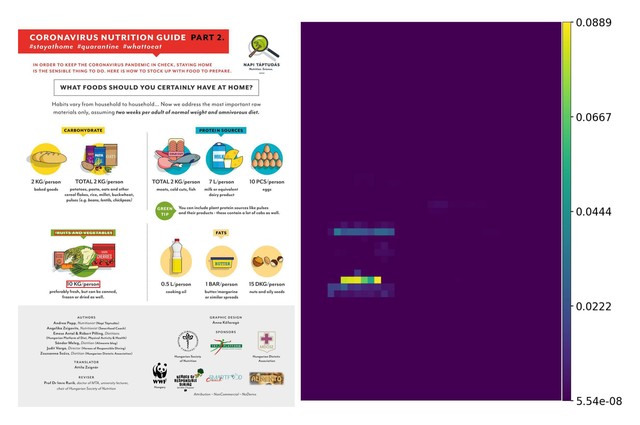
Shijie Zhou, Jihyung Kil, Ming Li, Jiuxiang Gu, Curtis Wigington, Rajiv Jain, Changyou Chen, Ruiyi Zhang Findings of ACL, 2026 paper OCR-free visual text grounding: a <g> token aggregates multimodal context, and its attention over image patches, merged across heads by a principled head-weighting scheme, localizes the evidence in text-rich images. |
|
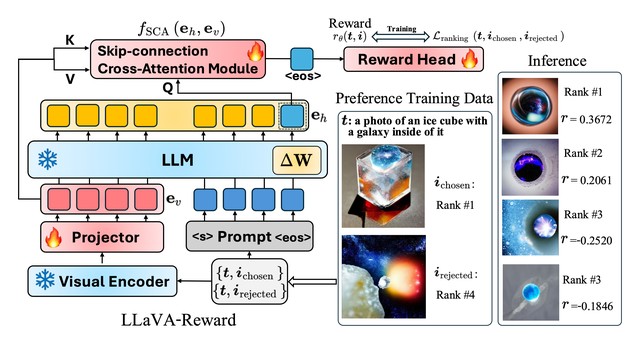
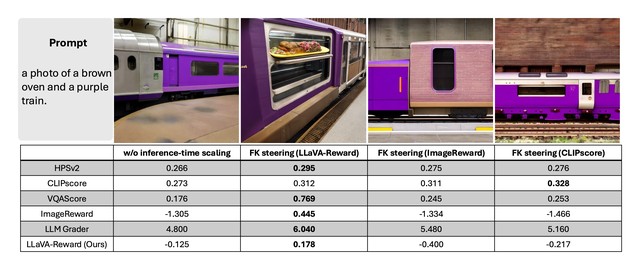
Multimodal LLMs as Customized Reward Models for Text-to-Image Generation
Shijie Zhou, Ruiyi Zhang, Huaisheng Zhu, Branislav Kveton, Yufan Zhou, Jiuxiang Gu, Jian Chen, Changyou Chen ICCV, 2025 arXiv / code LLaVA-Reward reads the hidden states of a pretrained MLLM directly, with a skip-connection cross-attention module, to evaluate text-to-image generations on alignment, fidelity/artifacts, safety, and overall ranking. |
|
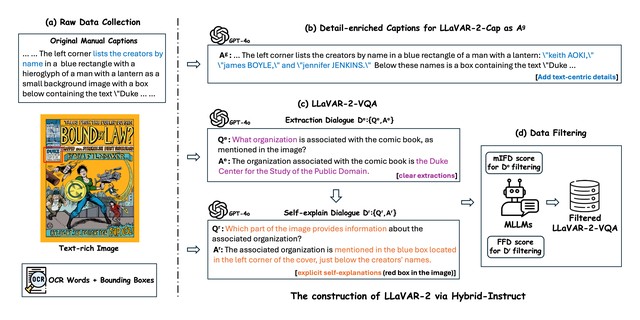
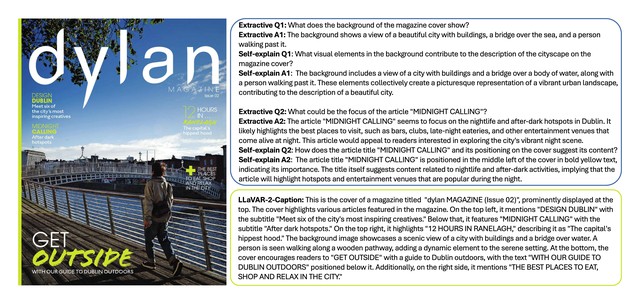
A High-Quality Text-Rich Image Instruction Tuning Dataset via Hybrid Instruction Generation
Shijie Zhou, Ruiyi Zhang, Yufan Zhou, Changyou Chen COLING, 2025 paper / arXiv / code LLaVAR-2: 424k instruction-tuning pairs for text-rich images, built by enriching human-annotated captions with GPT-4o and filtering the generated QA pairs with new mIFD and FFD scores. |
|
Simple Denoising Diffusion Language Models
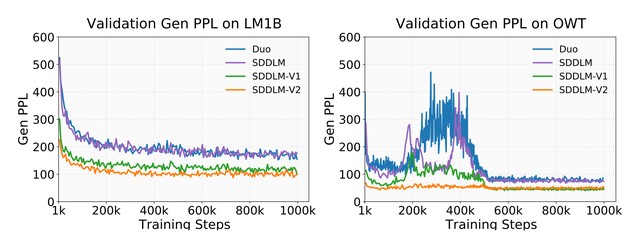
Huaisheng Zhu, Zhengyu Chen, Shijie Zhou, Zhihui Xie, Yige Yuan, Shiqi Chen, Zhimeng Guo, Siyuan Xu, Hangfan Zhang, Vasant Honavar, Teng Xiao ICML, 2026 arXiv / code A simplified denoising objective for uniform-state diffusion language models that stabilizes training and matches methods with more complex losses, plus a regularizer that counters corruption toward uniform outputs. |
|
Enhancing Diffusion Posterior Sampling for Inverse Problems by Integrating Crafted Measurements
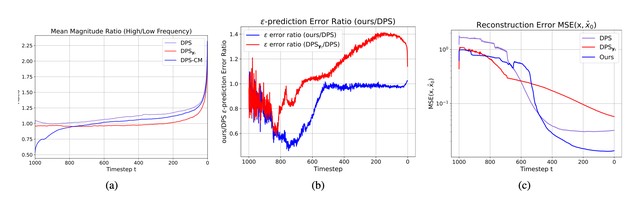
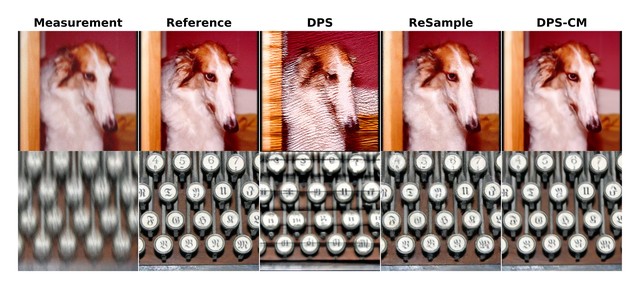
Shijie Zhou, Huaisheng Zhu, Rohan Sharma, Jiayi Chen, Ruiyi Zhang, Kaiyi Ji, Changyou Chen arXiv, 2024 arXiv / code Forming the posterior estimate with a crafted measurement, one produced by the reverse denoising process rather than the forward process, reduces accumulated errors when solving inverse problems with diffusion priors. |
|
Simple Distillation for One-Step Diffusion Models
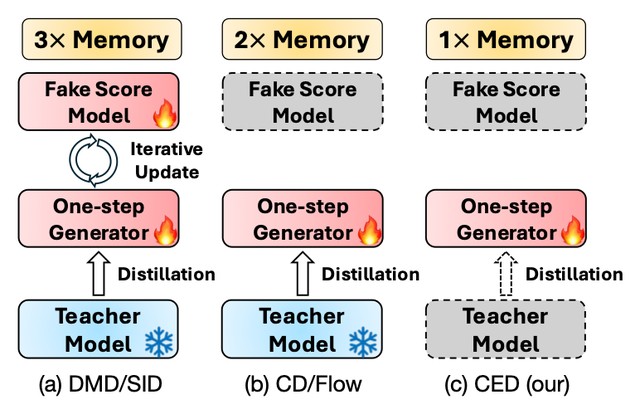
Huaisheng Zhu, Teng Xiao, Shijie Zhou, Zhimeng Guo, Hangfan Zhang, Siyuan Xu, Vasant G Honavar NeurIPS, 2025 paper Contrastive Energy Distillation distills a multi-step diffusion model into a one-step generator with a noise-contrastive objective on a joint energy-based model, with no auxiliary score model or iterative training. |
|
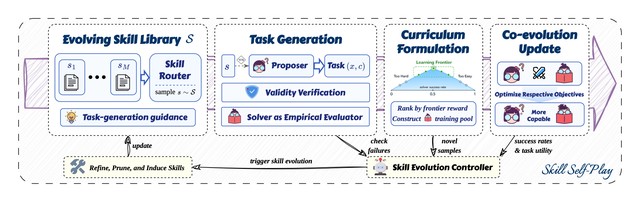
Skill Self-Play: Pushing the Frontier of LLM Capability with Co-Evolving Skills
Siyuan Huang, Pengyu Cheng, Haotian Liu, Tao Chen, Yihao Liu, Jingwei Ni, Shijie Zhou, Ziyi Yang, Gangwei Jiang, Mengyu Zhou, Yu Cheng, Xiaoxi Jiang, Guanjun Jiang arXiv, 2026 arXiv / code A proposer, a solver, and a dynamic skill controller co-evolve during RL; an evolving library of skills bridges reliable verification and open-ended task generation in LLM self-play. |
|
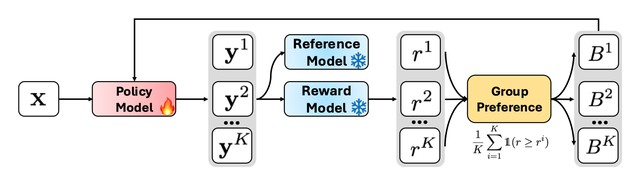
Reinforcement Learning for Large Language Models via Group Preference Reward Shaping
Huaisheng Zhu, Siyuan Xu, Hangfan Zhang, Teng Xiao, Zhimeng Guo, Shijie Zhou, Shuyue Hu, Vasant G Honavar EMNLP, 2025 paper / code Reshapes rewards with preference-based comparisons within groups of responses, giving a critic-free RL method that stays robust across reward model sizes and quality. |
|
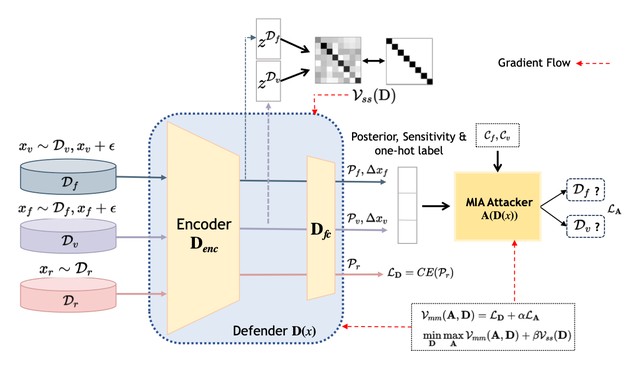
Discriminative Adversarial Unlearning
Rohan Sharma, Shijie Zhou, Kaiyi Ji, Changyou Chen arXiv, 2024 arXiv / code Machine unlearning as a min-max game: a membership-inference attacker tries to expose the forgotten data while the defender unlearns it, plus a self-supervised feature-space regularizer. |
|
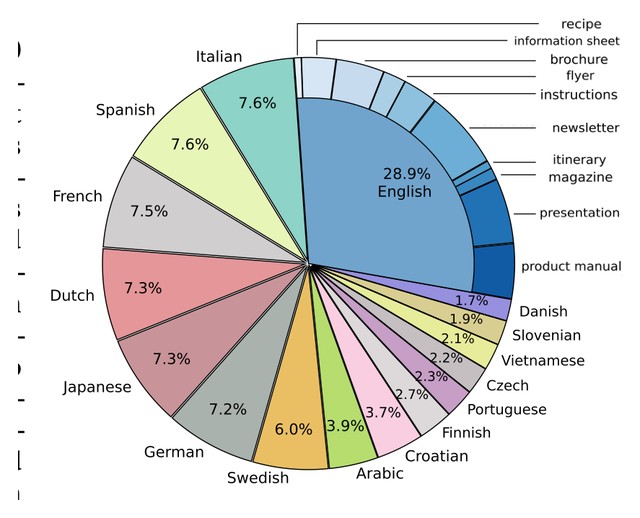
VisR-Bench: A Visual Retrieval Benchmark for Visually-Rich Documents
Jian Chen, Ruiyi Zhang, Ming Li, Shijie Zhou, Changyou Chen ICLR Workshop on Foundation Models in the Wild, 2025 OpenReview A question-driven benchmark for multimodal retrieval over scanned documents, spanning figures, tables, and text, in English and 15 other languages. |
|
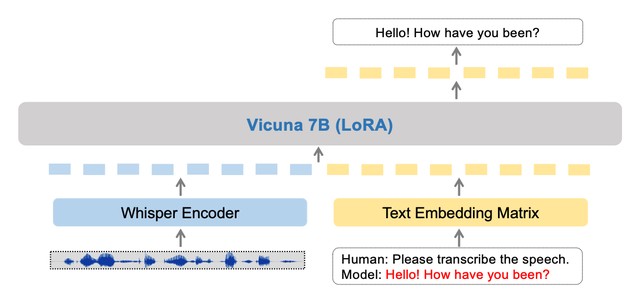
KidSpeak: A General Multi-purpose LLM for Kids' Speech Recognition and Screening
Rohan Sharma, Dancheng Liu, Jingchen Sun, Shijie Zhou, Jiayu Qin, Jinjun Xiong, Changyou Chen arXiv, 2025 arXiv A multi-task speech LLM for transcribing and screening children's speech, with phonetics-aware encoder training and a forced-alignment tool (FASA) for building cleaner training data. |
|
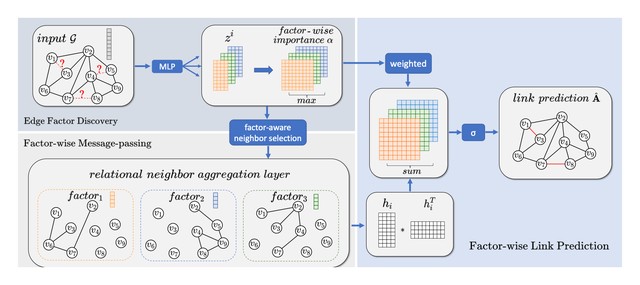
Link Prediction on Heterophilic Graphs via Disentangled Representation Learning
Shijie Zhou, Zhimeng Guo, Charu Aggarwal, Xiang Zhang, Suhang Wang arXiv, 2022 arXiv / code DisenLink learns disentangled node representations and performs factor-aware message passing, so that links formed by a single latent factor can be predicted on heterophilic graphs. |
|
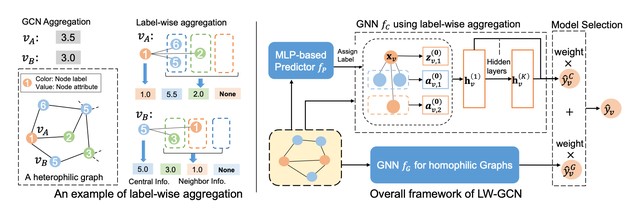
Label-Wise Graph Convolutional Network for Heterophilic Graphs
Enyan Dai, Shijie Zhou, Zhimeng Guo, Suhang Wang LoG, 2022 arXiv / code Label-wise message passing preserves heterophilic neighborhood context, and bi-level optimization automatically selects the right model for homophilic or heterophilic graphs. |
Experience | |
| Education | |
|
University at Buffalo
Ph.D. in Computer Science and Engineering. Advisor: Changyou Chen
|
2023 – Present |
|
The Pennsylvania State University
M.S. in Informatics
|
2021 – 2023 |
|
Soochow University
B.E. in Measurement Control Technology and Instruments
|
2016 – 2020 |
| Work Experience | |
|
Adobe Research, Research Intern
With Jihyung Kil. RAG-based efficient UI generation agent.
|
Sep 2026 – Present College Park, MD |
|
Qwen Large Model Application Team, Alibaba, Research Intern
With Pengyu Cheng. RL post-training for the base chat model; self-evolving language models for verifiable tasks.
|
May – Sep 2026 Hangzhou, China |
|
Adobe Research, Research Intern
With Ruiyi Zhang. GUI and document grounding and planning.
|
May – Nov 2025 San Jose, CA |
Teaching | |
|
Teaching Assistant
DS 420; CSE 574/474; CSE 676
|
|
Website template from Jon Barron. Last updated October 2026. |